Every metric on your cluster is a vital sign. Whaleal Platform tracks them continuously, and the moment one crosses the safe line, the signal reaches the right person immediately — instead of waiting for the business team to come knocking.
Live vital signs, refreshed continuously — the alert is already on its way the instant the line is crossed
Most teams stop at "we have a dashboard" — the charts look great, but nobody's actually watching them. Alerts get configured once and then either fire too often, training everyone to mute the channel, or fire too late, arriving well after the incident has already unfolded.
WAP collects metrics from both the host and the MongoDB instance layer — from basic CPU, memory, and disk I/O, to connection counts, replication lag, lock waits, and slow-query share — every metric recorded second by second, never sampled or estimated.
CPU · Memory · Disk I/O · Network Throughput
Connections · Queue Length · Opcounters · Cache Hit Rate
Election Frequency · Oplog Lag · Heartbeat Status
Slow Query Share · Lock Wait Time · Scan Efficiency
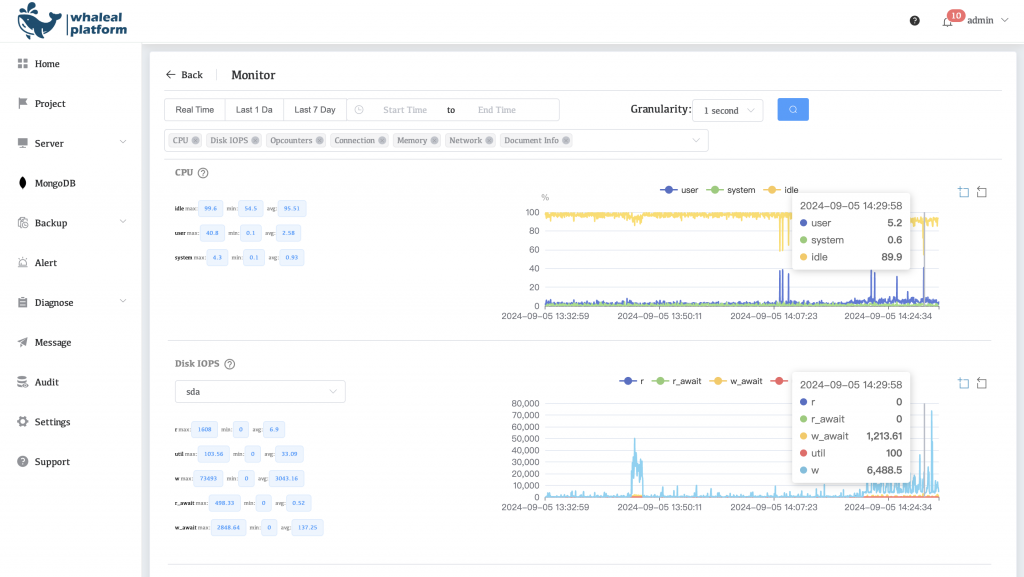
Every metric visualized — anomalies visible at a glance.
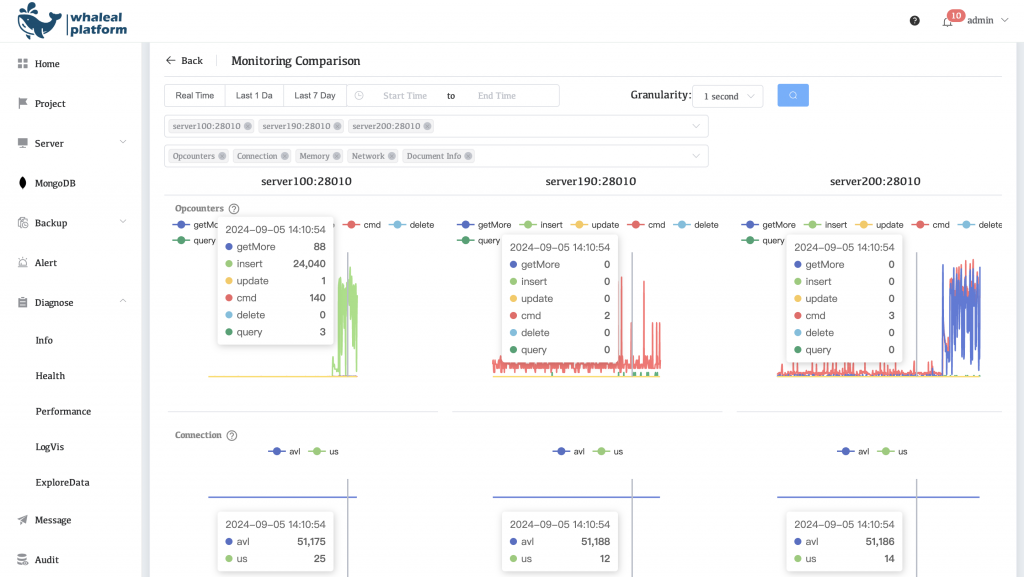
Cross-node, cross-cluster comparisons side by side.
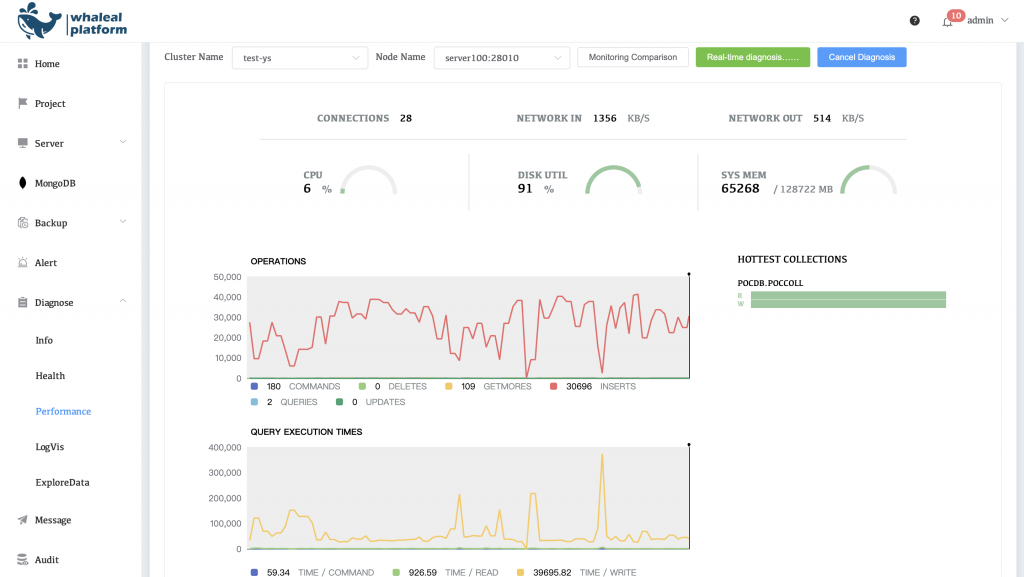
Health status refreshed live, risk flagged before it escalates.
A genuinely useful alerting system isn't really about the trigger condition — it's about tiered response. The same CPU spike happening during a quiet Tuesday afternoon and during peak traffic deserves a completely different response path.
Live values compared against thresholds
Info / Warning / Critical
The same issue won't spam you twice
Routed to the right channel by severity
Most alerting systems only shout "something's wrong" and leave the investigation to a human. WAP attaches context automatically — collapsing "spot the problem" and "find the cause" into a single step.
From reactive response to proactive early warning — that's exactly why Whaleal Platform's monitoring and alerting module exists.